Infrastructure · 2 April 2026
Agree what a finding is before building the dashboard
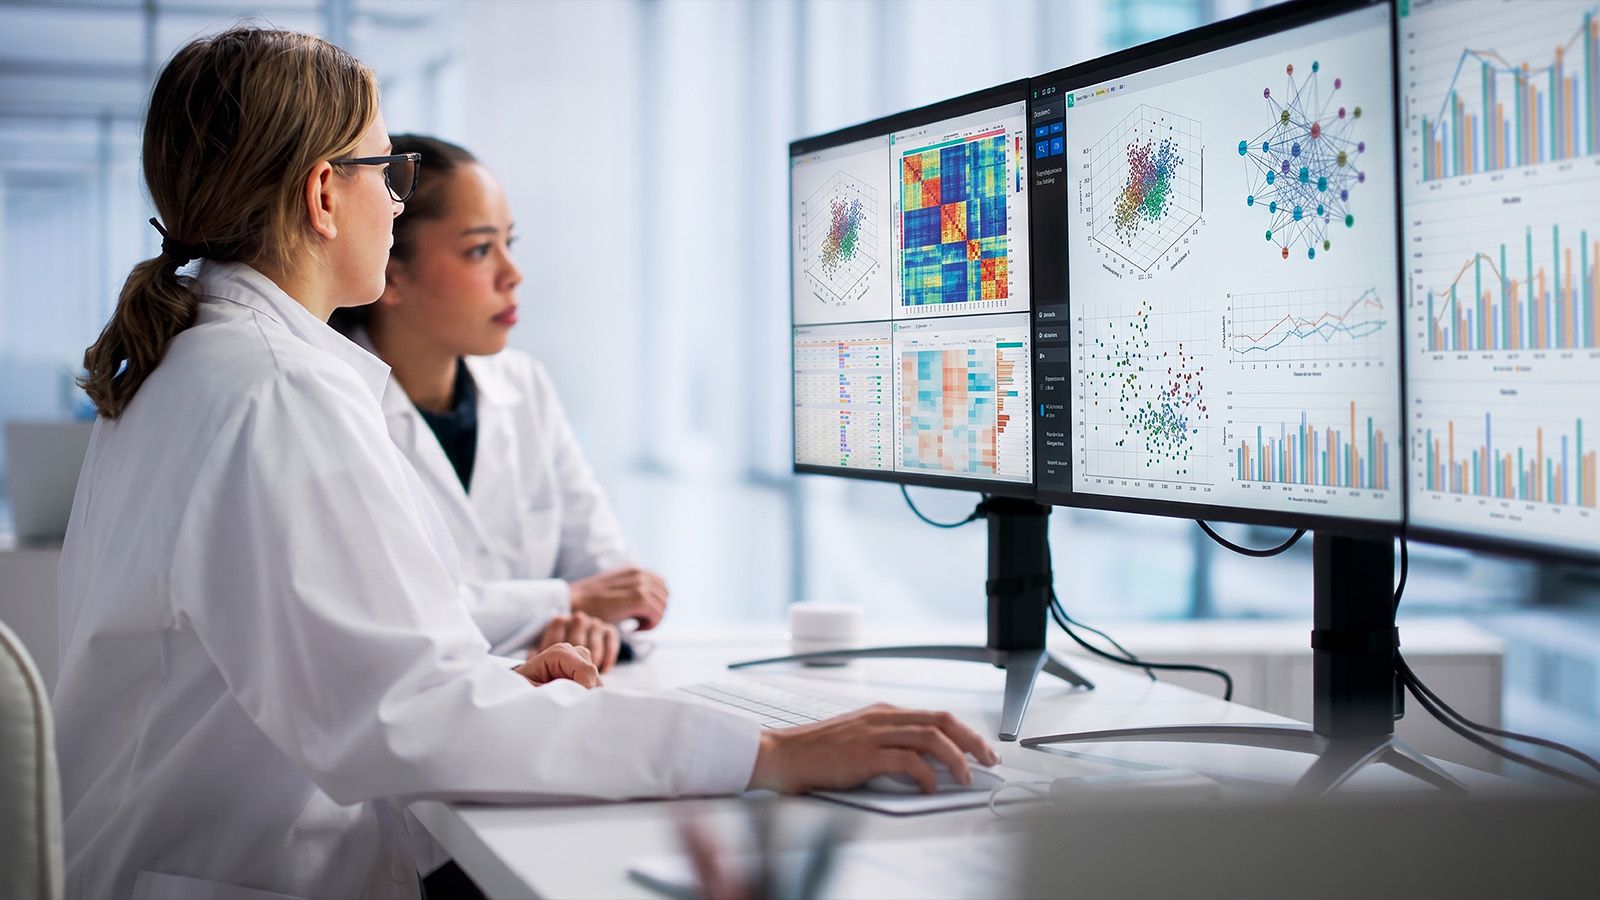
SysHealth gives one health view across mixed estates: AIX, Linux, storage, and network. Those sources don't agree on much. A few are modern exporters. Others are a command someone runs, with output that was never meant to be read as a metric.
My first instinct was to wait until every source behaved like the tidy ones. That wait doesn't end. In the meantime a team can see one symptom and miss how it connects to the rest, or miss that a source has gone silent. An empty chart reads as “nothing to report” unless the product says otherwise.
So before drawing a dashboard, I worked out what a finding is. A value can be one. A value that should be there and isn't can be one too. Inventory, configuration, and metrics went into one structure, so a gap shows up next to the thing it belongs to rather than in a separate tool.
The screens came after that. Which feeds are reporting, which have gone quiet, and which issues are still open is a better starting point for an operator than a wall of green. The raw output is still there for the investigation, just not on the front page.
None of this is a claim about any estate's uptime. It's how I'd shape the product again: normalise what I can, and treat what never arrived as information.
More insights
- Design the failed login path firstEngineering
- Connect the model to a real systemAI
- Use motion for state, then stopInterface
- Write the empty state before the full oneEngineering
- Leave a handoff the next developer can useEngineering
- Give an agent a boundary people can seeAI
- Build a company site for the next page, not the firstInterface
- Show the feed that stopped reportingInfrastructure
- Design for the return visit firstInterface